Put AI close to your people, data and operations. Seneca deploys and manages private AI for low-latency responses, controlled access and predictable operating costs, with less dependence on external AI services and international connectivity. Choose the models, capacity and integrations that work for your business.
One enthusiastic team, an automated workflow and thousands of requests can turn a useful AI service into an unpredictable bill. Bring model access, credentials and spending together before that happens.
Our managed AI broker is the gateway between your applications and their AI models. It gives you one place to govern connected usage across private infrastructure and hosted providers, so your people can use AI with clear access rules, accountable costs and agreed budgets.
Your people & applicationsAssistants · Workflows · Agents
→
Seneca AI brokerCredentials · Usage · Budgets · Routing
→
Your approved modelsPrivate infrastructure · Hosted APIs
Credentials under control
Keep provider keys out of individual applications
Seneca manages the provider credentials centrally and gives each application or team its own controlled access key. Rotate or revoke access, restrict the available models and avoid sharing one unrestricted account across the business.
Usage you can account for
Know where the tokens and money go
Track requests, input and output tokens, and estimated API spend by application, team and model. Allocate costs to the work that generated them and reconcile usage against provider billing. See which workflows earn their place and which need attention.
Budgets with boundaries
Set the allowance before the work starts
Set spending allowances and usage limits for teams and applications, with alerts as they approach their thresholds. Configure the broker to block new requests when its tracked budget is reached, then let an authorised owner decide whether to increase it.
The right model for the job
Keep expensive AI for work that needs it
Route routine jobs to efficient models and give demanding work access to frontier capabilities. Set approved routes and fallbacks, with sensitive workflows kept on private infrastructure. Control the balance between response time, capability and operating cost.
More useful AI. Fewer surprises.
A service team uses a private model to search internal procedures, while an approved analysis workflow uses a hosted frontier model. Each application has its own access and budget. The operations manager sees usage by team, spots a surge in automated requests and adjusts the allowance or routing before authorising more spend.
Seneca sets up the gateway, connects the agreed services and manages the controls. You get a clearer view of what AI costs and the freedom to choose where it runs. Budgets cover traffic routed through the broker; reporting separates metered API usage from private infrastructure costs.
Start with the requirement, then connect the right parts of the service.
01
Knowledge and document assistants
Find useful answers without searching every folder.
Private AI retrieves approved business information with its sources, helping staff prepare responses and resolve questions sooner. Access follows your organisation’s permissions.
02
Private deployment
Keep models and business knowledge within your chosen environment.
We host and manage the AI around your privacy and capacity needs. Local processing gives you control over the data boundary; any retained external integrations are made explicit.
03
Workflow integration
Release time spent copying, drafting and preparing information.
We connect AI to the applications your team uses, keeping source information and the right approvals in the workflow. Staff spend more time on exceptions and decisions that need their attention.
Why private AI?
Performance, privacy and resilience. On your terms.
Give your business control over how AI performs, what it costs and where its information goes. We design and manage the service around the work you need to improve.
Low latency & performance
Keep the response close to the work.
When people or machines need an answer, a round trip to a remote AI service adds delay. Local inference processes requests close to your users and data, reducing network latency and giving you direct control of the capacity serving the workload.
Seneca matches models, acceleration and memory to the response times and number of simultaneous users you need. An engineer retrieving instructions, an operator checking an image or a team processing documents gets a service designed around the job.
Privacy
Keep business knowledge in your environment.
Customer records, commercial documents and operational knowledge should stay within the boundaries you choose. Private AI brings the model and its supporting information into your environment, reducing the need to send sensitive material to external AI services.
We connect the assistant to your documents and applications with access tied to the user. Your team can put valuable information to work while you control where it is processed, stored and retained.
Security & control
Decide who can use it—and what it can reach.
AI becomes part of your business infrastructure when it can search records or take actions. Seneca designs access controls, network separation, logging and managed updates around those capabilities, so the service operates within your security model.
You control administration, permissions and connections to other systems. Security management sits alongside the AI service, giving your team a clear way to govern its use and investigate activity.
Cost predictability & token consumption
Plan for useful work, not a growing token bill.
Long documents, repeated questions and automated workflows increase the amount of text an AI model processes. Tokens are the chunks of text it reads and generates; with metered APIs, growing token consumption can make monthly bills harder to predict.
Self-hosted models let you run local inference without an external per-token API charge. We plan hardware, power, licences and management around your expected usage, making capacity and operating costs visible as more teams put AI to work.
Resilience
Keep essential AI close when external services fail.
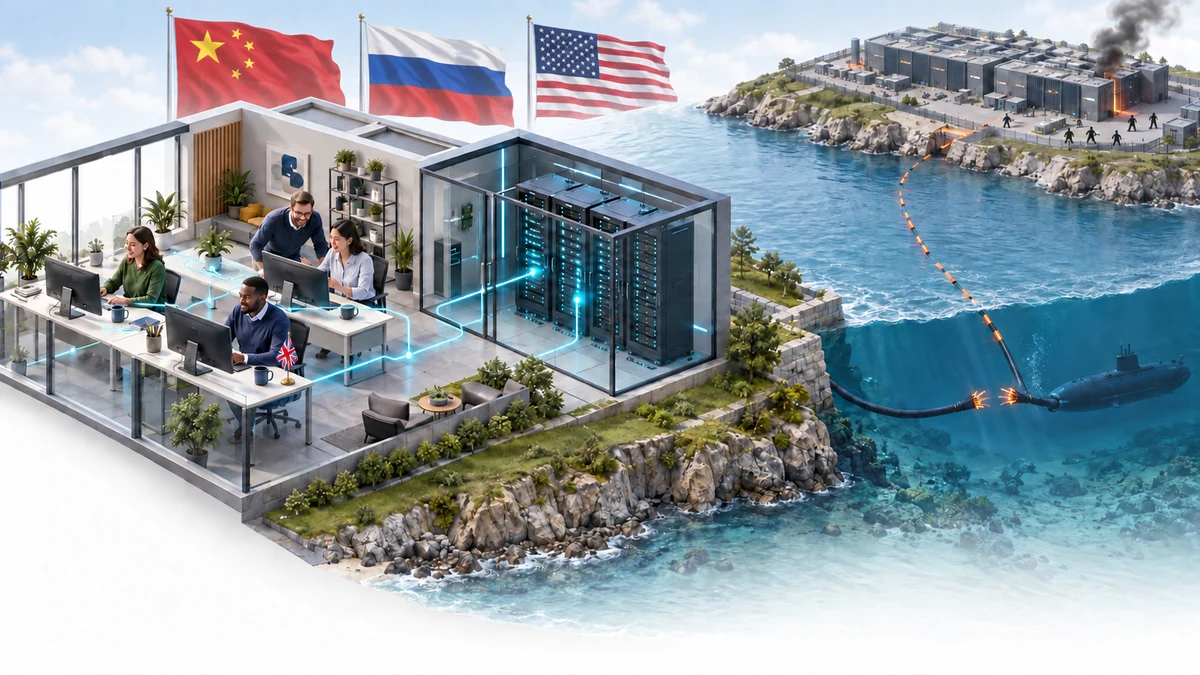
Submarine cable damage or deliberate attacks, international connectivity disruption and hyperscale data-centre outages can interrupt access to remote AI. Bringing essential models, knowledge and applications onto your estate reduces that dependence for the work you need to keep running.
Seneca designs the local service around its supporting systems, including sign-in, power and recovery. Essential workflows can continue locally through an external outage when their dependencies are local too, with external integrations brought back into use as services recover.
Flexibility
Choose the model that fits the job.
Different tasks need different models and levels of compute. A document assistant, an image inspection service and an automated workflow should each use the capabilities that suit the work, with room to change as your business develops.
We help you select compatible models, connect your applications and add capacity as demand grows. Start with a focused service or deploy across the business, using private and selected cloud services where each makes commercial sense.
Choose from open-source and open-weight AI for your own infrastructure, with hosted models available where they suit the work. These examples show the range; Seneca matches the model, compute and integrations to your business.
Run on your infrastructure
Keep inference close to your people and data. We manage deployment, access and updates, with the model licence and hardware matched to your use.
OpenAI
gpt-oss-120b
Private deployment · Open weights
Reason through complex work
Analyse business documents, support technical teams and connect reasoning to your internal tools. Keep the model and its working data inside your own environment.
OpenAI
gpt-oss-20b
Private deployment · Open weights
Bring AI closer to the team
A smaller reasoning model for local assistants and focused workflows. A practical option when you want responsive AI with a smaller infrastructure footprint.
Meta
Llama 4 Scout
Private deployment · Open weights
Make more of your documents
Work with text and images in a private assistant. Help teams explore manuals, reference material and operational knowledge without sending every request to an external service.
Meta
Llama 4 Maverick
Private deployment · Open weights
Connect knowledge across the business
Multimodal AI for assistants that work across documents, images and business applications. Build a shared knowledge service around your own information and access rules.
Mistral AI
Mistral Large 3
Private deployment · Open weights
Put a capable assistant to work
An open-weight text and vision model for demanding business applications. Bring document understanding and conversational assistance into the same managed environment.
Mistral AI
Mistral Small 4
Private deployment · Open weights
Balance capability and running cost
Combine everyday instruction following, reasoning and coding in one efficient model. Support regular team workflows with capacity sized around your actual workload.
Mistral AI
Ministral 3 14B
Private deployment · Open weights
Take AI to the edge
A compact text and vision model for local applications. Put assistance near the people, equipment and information that need it, including sites with limited external connectivity.
Qwen
Qwen3-32B
Private deployment · Open weights
Support multilingual teams
Use local reasoning, language and coding capabilities across business workflows. Help staff work through technical questions and routine information tasks in their own environment.
DeepSeek
DeepSeek-R1
Private deployment · Open weights
Put private reasoning to work
Give technical and analytical teams a locally hosted reasoning model for problem solving, coding and working through complex information. Seneca sizes the deployment around response times and the number of people using it.
Google
Gemma 3 27B
Private deployment · Open weights
Turn text and images into useful answers
Build assistants that work with written information and visual inputs. Support document queries and image-led workflows on infrastructure managed for your business.
Open AI ecosystem
Hugging Face. A wider world of possibilities.
Different jobs need different models. A document assistant needs to find the right information; an inspection system needs to understand images; a service desk may need speech recognition. The Hugging Face ecosystem brings model repositories, datasets and tools together, opening up far more choice than a single chatbot.
Seneca selects suitable models, checks their licences and brings them into a managed deployment. We connect the runtime, compute and access controls, then maintain the chosen versions as part of your AI service. You get specialist capabilities around your business, with a clear route to change models as your needs evolve.
Language & reasoningDocument search & embeddingsVision & inspectionSpeech & transcriptionModel adaptationPrivate model serving
Frontier models · Hosted integration
Leading AI. One managed connection.
Use OpenAI, Claude, Grok and Gemini alongside your private models. Seneca connects your applications to the appropriate service, with shared controls for access, usage and budgets.
These models run with their providers and are billed for usage. You decide which workflows can send information externally; sensitive work can stay with your locally hosted models. ChatGPT subscriptions are separate from OpenAI API usage managed through the broker.
OpenAI
GPT-6 Astra
Hosted API · Usage-based pricing
Advanced reasoning for demanding work
Connect complex research, coding and document workflows to OpenAI’s hosted flagship. Give approved applications access through the broker, with their usage attributed to the right team.
Anthropic
Claude Fable 5.1
Hosted API · Usage-based pricing
Work through complex, multi-step tasks
Support demanding reasoning and extended agent workflows with Claude. Bring document analysis and connected tools into a managed service with controlled access and spending.
Grok
Grok 4.7
Hosted API · Usage-based pricing
Connect reasoning, coding and tools
Give selected applications access to Grok for technical work and tool-driven workflows. Enable external search where the task needs current information, under your agreed data and spending rules.
Google
Gemini 3.8 Flash
Hosted API · Usage-based pricing
Bring AI into busy business workflows
Support coding, agents and complex enterprise tasks with Gemini. Route approved work through the same managed gateway so teams can use another model without another unmanaged set of credentials.
See how everyday problems become connected work, less administration and greater control.
01
Find the answer while the work is in front of you
Engineers lose valuable working time searching folders for manuals, service notes and previous fixes. A private AI assistant brings that knowledge into the conversation, finding relevant passages and returning an answer with links to the source. The engineer can check the instruction beside the machine instead of breaking off to search another system.
Seneca connects the assistant to your approved information and existing access permissions, running the model and knowledge index on your infrastructure. Your team spends less time hunting for answers, experienced staff face fewer repeat questions, and valuable operational knowledge stays under your control.
A customer asks a question that needs product information, account history and a previous service record. Instead of opening several systems and piecing together a reply, the adviser uses a private AI assistant to retrieve the relevant details and prepare a response. The source information stays alongside the draft, so the adviser can check it and send a clear answer.
Seneca connects the assistant to your service workflow and hosts the AI within your agreed data boundary. Staff spend less time searching and rewriting, customers spend less time waiting, and your business retains control of the information behind every response. You decide which actions need approval and who can access each record.
Delivery notes arrive as scans, photographs and PDFs, leaving goods-in staff to retype references and quantities. Private AI extracts the details, matches them to the expected delivery and highlights discrepancies for the receiving team. The original document remains attached to the record, keeping the evidence close to the decision.
Seneca connects that work to your stock or business application on infrastructure you control. Routine documents move through with less manual entry, staff focus on exceptions, and the next team gets the information sooner. Commercial records stay within your chosen environment instead of being scattered across separate AI services.
We help turn the opportunity into a business case.
We assess your estate, AI workloads and expected usage, then help build the business case. We compare token consumption and external service charges with private compute, power, licensing and support costs, alongside the value of faster responses, privacy and continuity. You get a clear view of the capacity and running cost needed to support your team.
Start with a focused deployment and expand, or move ahead with a full programme. We shape delivery around your priorities, budget and readiness, and manage the work with you.
An assistant delivers more value when it can work inside the applications your team uses. The Sovereign Business Platform connects private AI, records and workflows so useful information reaches the next step without another copy-and-paste handover.
Seneca deploys and manages the environment around your business. You gain a joined-up service with control over data, access and the infrastructure behind it.
Common questions
Straight answers to your questions.
Make deployment, costs and responsibilities clear from the start.
How does private AI change token costs?
Tokens are the chunks of text a language model reads and generates. With self-hosted models, local inference can run without an external per-token API charge. We plan compute capacity and operating costs around your volume, model size and simultaneous users, and identify any model licence or retained API charges.
Can private AI keep working during an internet or cloud outage?
Yes, when the model, data, sign-in and required applications run locally. We design essential workflows to continue through external disruption, with local power, backup and recovery arrangements supporting the service. Workflows that still call external systems depend on those connections.
Can we change models or add capacity?
Yes. We select compatible models and serving tools around your workloads, and plan capacity for growth. You can introduce specialist models, replace a model as your needs change, or retain selected cloud services as part of a hybrid design.
What is a private LLM?
A large language model is an AI model that works with language. A private deployment runs the selected model within an agreed environment, with defined access and data-handling rules.
Does all information stay in our environment?
We can host the model, knowledge index and logs within your environment. We identify any external integration and agree its data boundary with you, so private hosting is reflected in the complete service design.
Can it work with our documents?
Yes. We connect the assistant to approved documents, preserve permissions and return answers with sources. Seneca prepares the integration and checks answer quality around the work your team needs to do.
Can we automate entire processes?
Yes, suitable workflows can be automated end to end. We design approval steps around the decisions involved, and can deliver a focused application or a wider programme.
Bring us the problem you want to solve.
We’ll discuss the requirements and the right next step.